November, 11 2026
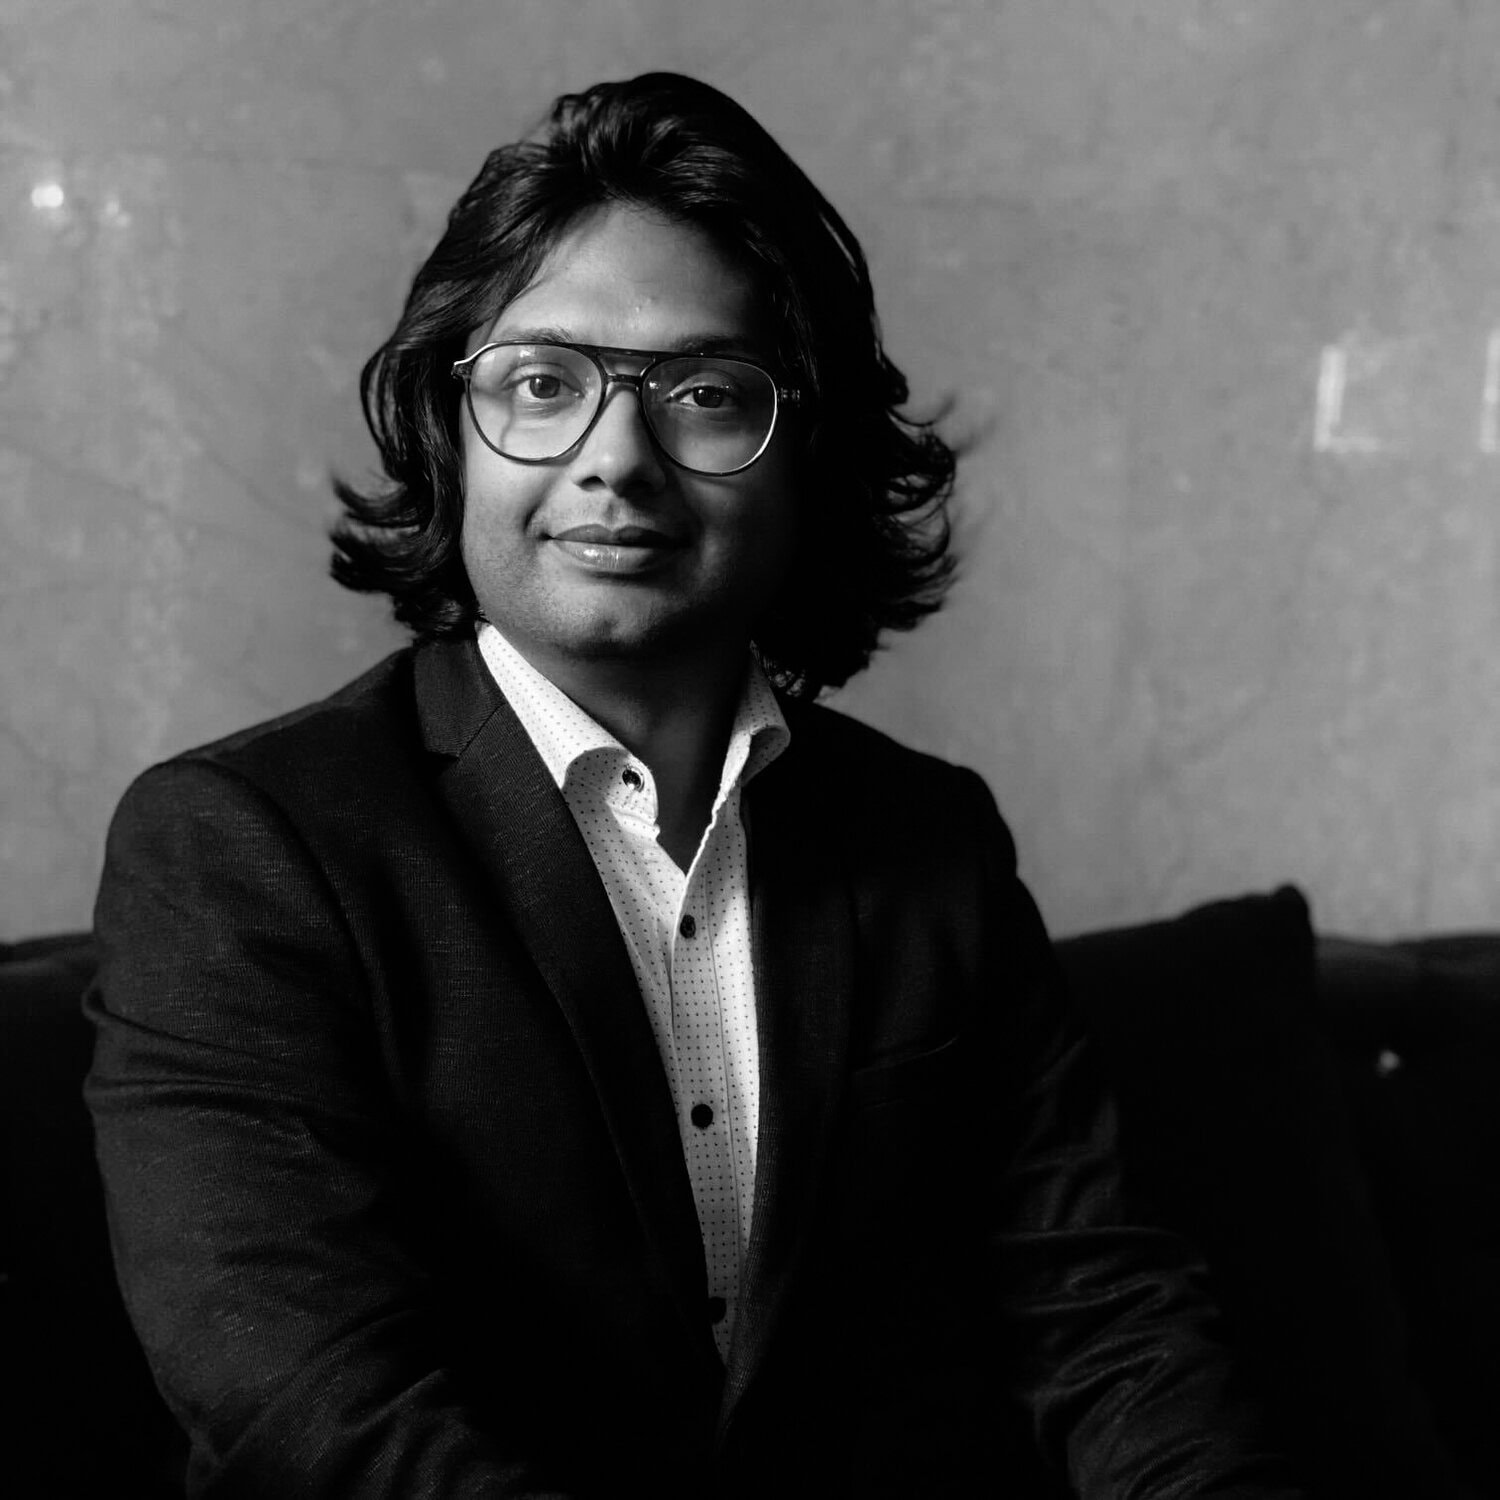
Mitesh Agrawal – CEO, Positron AI
Why AI’s Next Bottleneck Is Memory: Mitesh Agrawal, CEO of Positron AI
Listen on:
The AI infrastructure race has largely been framed as a contest for more compute: bigger GPUs, more chips, and larger data centers. But as AI shifts from training models to running them at scale, a different constraint is emerging. Inference workloads, particularly for frontier models, reasoning models, long context windows, and video generation, depend heavily on how quickly data can move through memory and how much memory each chip can hold. GPUs are exceptional at the math behind training, yet during inference they often use only 30 to 50 percent of their available memory bandwidth. At the same time, data centers are constrained by power, cooling, and supply chain bottlenecks for advanced components like high bandwidth memory. For enterprises and cloud providers spending hundreds of billions of dollars on AI, efficiency per chip, per watt, and per dollar has become a strategic priority.
On this episode of The Reboot Chronicles Podcast, we sit down with Mitesh Agrawal, CEO of Positron AI, the inference focused silicon company that has raised more than one billion dollars over the past year, including an 875 million dollar Series C. Mitesh, the former co-founder and CEO of Lambda, explains why memory bandwidth and capacity are becoming the defining constraints of AI inference, how Positron’s architecture delivers more than 90 percent memory bandwidth utilization and up to 2.3 terabytes of memory per chip, and why building on commodity memory gives the company a supply chain advantage. He also breaks down the size of the inference market, what is really happening to token costs, and why silicon companies must reboot themselves with every new chip generation.
The Memory Problem Inside AI Inference
Positron’s founding thesis, developed by co-founders Thomas Sohmers and Edward Kmett in 2023, was that as AI models grew larger, memory bandwidth would become a bottleneck for inference. That was before reasoning models and a mixture of expert architectures became mainstream. As context windows expanded, a second constraint emerged: memory capacity, the ability to hold model weights, context, and cached data on as few chips as possible.
Agrawal explains the technical distinction simply. Training and the prefill stage of inference rely largely on matrix to matrix math, which GPUs handle extremely well. The decode stage of inference, where models generate output, relies more on matrix to vector math and requires moving enormous amounts of data. That puts pressure on memory bandwidth, and GPUs typically use only 30 to 50 percent of it during these workloads. Positron’s architecture is designed to use more than 90 percent of available memory bandwidth. Its external memory system also scales to 2.3 terabytes per chip, compared with roughly 288 to 500 gigabytes on the latest accelerators from NVIDIA and AMD. “We can hold very large models in a very small number of chips,” Agrawal said, enabling faster response speeds while maintaining strong throughput per dollar.
Agrawal is careful about how he frames the competitive landscape. Rather than positioning Positron as an NVIDIA challenger, he sees an opportunity for inference companies to win specific workloads as NVIDIA faces supply chain constraints. “Until some company can come in and claim at least ten percent, twenty percent of their revenue, I don’t think we should call anyone an NVIDIA competitor yet,” he said.
Solving for Supply Chain and Data Center Reality
According to Agrawal, every large customer conversation comes down to two practical questions: can Positron manufacture at meaningful scale, and can it give the customer more options for deploying computers in power constrained data centers? Positron’s answer to both is built into its design. While NVIDIA, Google’s TPUs, and AMD rely on high bandwidth memory and advanced packaging that are in short supply, Positron uses commodity memory and organic substrates. “If you’re using things like high bandwidth memory, you’re going to be behind them in the supply chain line,” he explained. Using more widely available components allows the company to scale production faster.
Efficiency is the other advantage. Because Positron focuses on inference, it can trade off some of the computing capability needed for training in exchange for lower power consumption and more tokens per watt. That allows its systems to run in existing air cooled data centers with rack densities of 10 to 40 kilowatts, facilities that cannot support the latest high density GPUs. With power increasingly scarce, that flexibility opens up capacity in older facilities, telecom sites, and enterprise data centers. Positron’s announced customers include Oracle and Jump Trading, the quantitative trading firm, which is interested in deploying Positron systems in air cooled facilities closer to financial exchanges. Agrawal sees growing interest in deploying inference compute on premises, particularly for security and low latency use cases, though he does not view it as a wholesale move away from the cloud. Instead, with cloud capacity largely sold out, companies are finding additional ways to bring compute online.
Raising Over a Billion Dollars to Build at NVIDIA’s Pace
Positron raised its capital through traditional venture funding rather than strategic investments from chipmakers, and is backed by Silicon Graphics veterans Jim Clark and Forest Baskett. The company has not yet used its Series B capital, and the Series C will fund two priorities. The first is product cadence. Agrawal points to NVIDIA’s ability to deliver new silicon every 12 to 18 months as one of its strongest competitive advantages. “The market trusts them to come out with the new silicon,” he said. Positron needs to earn that same trust by building multiple generations of chips in parallel.
The second priority is production scale. Positron operates as a fabless semiconductor company, working with TSMC for chip fabrication and with manufacturing partners to build systems. A strong balance sheet allows it to back large purchase orders with suppliers of memory, power modules, cables, networking, and other components, alongside customer orders. The company has grown from 20 people a year ago to 111 today, primarily engineers. Its first generation product, which competes with NVIDIA’s H100, has sold more than the company expected, and its next generation silicon is scheduled for next year.
Sizing the Inference Market and the Truth About Token Costs
Agrawal offers a conservative way to size Positron’s opportunity. Of the roughly one trillion dollars in total AI infrastructure spending projected this year, about half goes to physical data center and power infrastructure. The remaining 500 billion dollars goes into data center equipment, with roughly 350 billion dollars going to NVIDIA. If at least half of that new compute is used for inference, the inference market is approximately 175 billion dollars this year, and growing 80 to 100 percent annually. More than 90 percent of it currently runs on NVIDIA. “One percent is a couple of billion dollars. Five percent is obviously ten billion dollars,” Agrawal said. Positron’s focus is on serving very large frontier models and decode heavy workloads like video generation at significantly higher speeds than today’s typical 30 to 50 tokens per second.
For executives watching AI costs rise, Agrawal clarifies what is happening. Newer chips are more expensive, but they also produce far more tokens. On an apples to apples basis, running the same size model today costs significantly less per token than it did a year ago, and today’s models are more capable. Total spending is still increasing because companies are using ten times as many tokens and moving to larger, more intelligent models. Unlike traditional software priced per seat, AI consumption can grow far faster than headcount, which is why efficiency at the infrastructure level matters so much.
The Reboot: From Lambda to Silicon
Agrawal spent nearly eight years as co-founder and CEO of Lambda, the AI cloud company, building data centers, securing power, and deploying tens of thousands of GPUs as cloud services. Although he studied chemical engineering and semiconductor fabrication, he had never worked in chip design. While building massive clusters at Lambda, he saw the memory constraint firsthand, not initially through reasoning models, but through video generation, where generating a ten second video required splitting work across large numbers of GPUs to access enough memory bandwidth and capacity. He recognized that Positron’s architecture was designed to solve exactly that problem.
Leaving a fast growing company he had helped build was not easy, but he wanted to innovate directly in silicon. He credits co-founder Thomas Sohmers, who started his first chip company at 17 and taped out silicon on an advanced TSMC node at 19, as well as Sohmers’ trust in him. Agrawal also believes the reboot never really ends for a silicon company. Intel once had years between major architecture changes. Today, AI model architectures evolve so quickly that companies must develop several chip generations simultaneously and anticipate where the market is heading rather than reacting to it. “After every silicon, you’re rebooting your company,” he said. For Positron to become a multi decade company like NVIDIA, AMD, Intel, or Cisco, he believes it will need to deliver four, five, even ten successful products over the next decade.